Fundamentals of Machine Learning · Digital lecture note
Lecture 5 – Naive Bayes, kernel density and k-NN
Makine Öğrenmesinin Temelleri – Naive Bayes, kernel density ve k-nn
- Course
- Fundamentals of Machine Learning (ELM472)
- Semester
- Semester 7 · Fall 2024–25
- Format
- PDF · 3 pages · 0.1 MB · handwriting-style LaTeX
- Language
- Turkish
- Original note
- Ders-5.pdf
Open the PDF (0.1 MB)LaTeX source (.tex)Original handwritten note
Notice: The digital notes were created from the handwritten notes with the help of Claude (Anthropic); they are meant as a supplementary resource and may contain errors. Always rely on the original notes and the official course materials.
What is in this note?
Section headings of the note (in Turkish):
- Kitapta non parametrik kısımlara gireceğiz
Text of the note
Show as plain text (Turkish; formulas and drawings are not included)
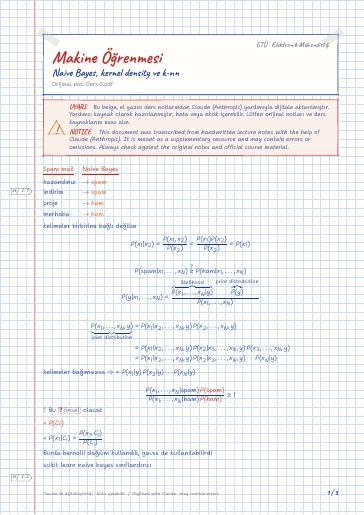
kelimeler birbirine bağlı değilse
Burda bernolli dağılım kullandık, gauss de kullanılabilirdi
scikit learn naive bayes sınıflandırıcı
Kitapta non parametrik kısımlara gireceğiz
olasılık dağılımı için kullanılabilir o zaman ∫ f(x) = 1 olmalıdır.
→ varyansa göre varyans büyükse h
kernel Approximation fonksiyonlar birbirinin aynısı
Burda bütün verileri tutmamız lazım k-nn de
distance metriği ile çözersek
2-nn için en büyük ikincisi